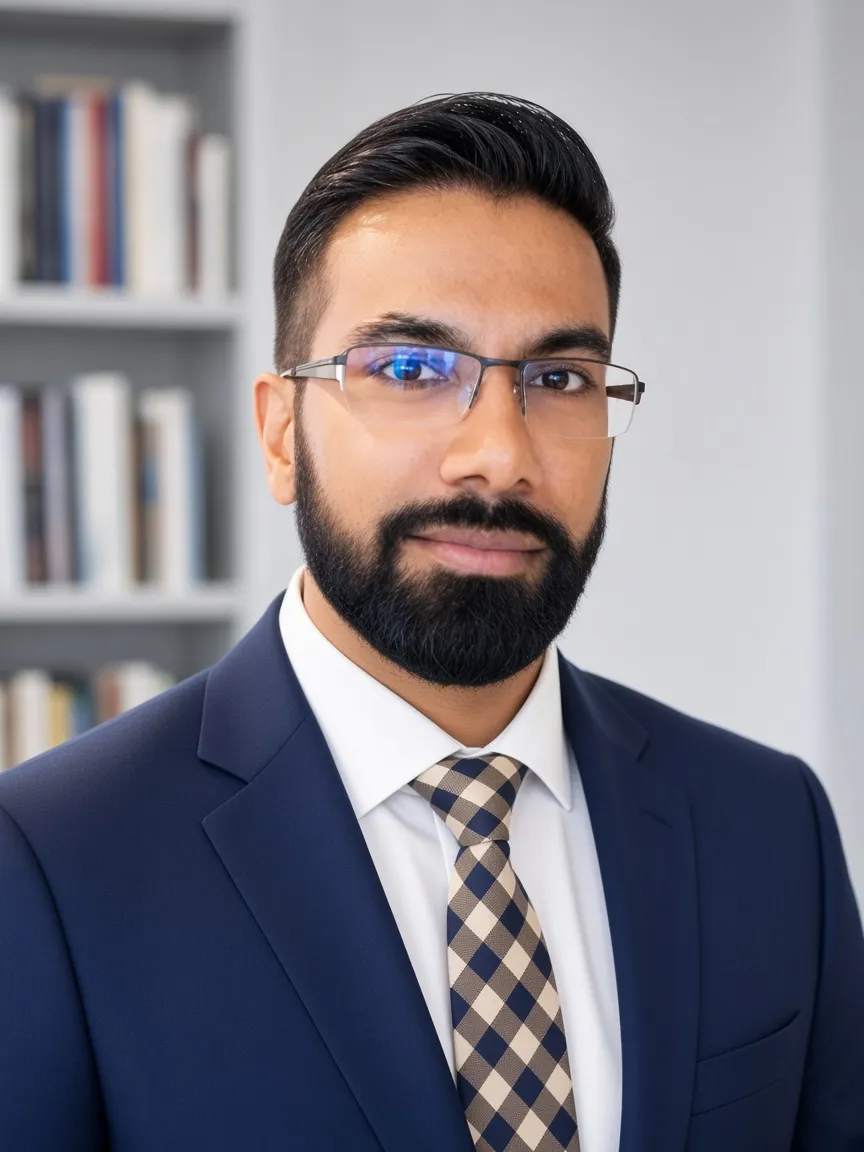
Hey. I’m Sunil Ramlochan.
I got hooked on making early generative models actually useful. Still at it — teaching in public, shipping systems that hold up.
Shaping What Came Next in AI
Light years in AI
I didn’t really set out to build a brand around prompt engineering.
I just got hooked on figuring out how to make the early generative models actually useful.
Back then it was GPT-2, GPT-Neo, GPT-J, and whatever else you could get your hands on and somehow convince to do something useful.
If anyone remembers that far back.
I know. Light years in AI.
Everything around the model
The prompting itself was only one part of it.
The harder part was everything around the model. Collecting good examples. Organizing them. Building templates. Figuring out how to store and retrieve information. Versioning prompts. Routing tasks. Testing outputs. Building tools around the model so you could get something reliable instead of just crossing your fingers and hoping the next completion didn’t go completely off the rails.
Very advanced technology.
Prompt engineering, at least to me, was never just about coming up with a clever sentence to put into a chat box.
A domain and no master plan
So on 6 March 2022, I registered promptengineering.org.
At first it was really just a labour of love.
There was no grand master plan.
I wanted a place where I could research this stuff, write about what I was learning, and help people understand how to use generative AI in a practical way.
Over time, that became PromptEngineering.org.
I started building libraries like Partials, Agents and Miniscripts, and I kept writing.
A lot.
Probably more than was sensible.
As the work moved beyond prompts and into actual agent systems, I later started AgentEngineering.org. And when companies wanted help actually building and implementing these systems rather than just reading about them, that eventually led to Axys Analytics.
Past “be specific”
The interesting thing is that, after a while, I wasn’t really writing about “prompting techniques” anymore.
You can only write so much about “be specific” and “give the model examples.”
I was much more interested in everything that had to exist around the model for these systems to work properly.
How do you break work into smaller pieces?
How do you separate knowledge from memory?
How do you get a supervisor to coordinate specialist agents?
How do you decide what context each agent should actually see?
How do you validate the output instead of simply trusting the model because it sounded confident?
A recurring problem, as it turns out.
Maps before the vocabulary
That led to things like GAINs, where a coordinator works with specialists and validators.
I wrote about a broader LLM agent stack built around a Prompt Recipe, Interface, Tools, Knowledge, Memory and a supervisor loop.
I kept coming back to the idea that memory and knowledge are not the same thing.
They still aren’t, despite our occasional attempts to pretend otherwise.
I explored some of the limitations behind that more deeply in Statistical or Sentient.
And with ideas like HCIN, I was thinking about something else that has become increasingly important: giving a model only the context it actually needs instead of dumping half the company into the context window and hoping intelligence emerges.
A surprisingly popular architecture.
New names for old problems
Looking back, a lot of that work was pointing toward what people now describe as context engineering, harness engineering, agent orchestration and agent engineering.
The terminology changed.
The models got much better.
The tooling became far more sophisticated.
And naturally, we invented several new names for some very old problems.
But the underlying questions stayed surprisingly similar.
How do you give the model the right information?
How do you structure the work?
How do you coordinate different components?
How do you check that the thing actually did what you asked it to do?
Planks, then a bridge
A number of founders and builders found that work along the way. Some used it as a starting point for things they were building, and I’ve had the chance to speak with and advise quite a few of them.
I don’t say that to take anything away from what came afterwards.
Quite the opposite.
A lot of the people who built on these ideas took them much further. Their work has been just as important, and in many cases genuinely changed what became possible.
That’s how this field works.
Someone puts down a few planks, someone else builds a bridge, and six months later Twitter gives the bridge a new name.
Then keep going
My point is simply that two or three years ago, while most of the conversation was still centred on better prompts and chat techniques, some of us were already trying to map out what came next.
And yes, two or three years ago sounds ridiculous in AI terms.
Basically ancient history.
The questions were already there.
How do you build the system around the model?
How do you make it reliable?
How do you give it the right information at the right time?
How do you coordinate multiple models and tools?
How do you turn all of that into something people can actually use?
That has really been the thread running through everything I’ve done since.
Learn it.
Write about it in public.
Build it.
Break it occasionally.
Figure out why.
Then keep going.
Cited by


A few numbers, if you like those
None of this is a pitch deck. Just the parts that are easy to count.
- 20+
- Years bouncing through marketing, security, design, analytics, and AI
- $30MM+
- Recovered or saved for businesses over about five years
- 20k+
- People subscribed to PromptEngineering.org
- Cited
- Across universities, government, and industry — not a trophy list
Anyway
If you want to talk, talk
Consulting, speaking, or PromptEngineering.org stuff — LinkedIn is the easiest door. Email’s on request.